October 19, 2026
I Cleaned Duplicate Shopify CSV Rows Before a Contractor Handoff
A practical browser workflow for reviewing, deduplicating, sorting, and handing off a Shopify CSV without uploading catalog data.
I needed to hand a contractor a Shopify catalog extract, but the file had been assembled over a few exports. There were duplicate handles, rows that only differed in a blank note field, and a few repeated variants that might have been legitimate. Sending it as-is would turn a small handoff into a mystery project. Opening it in a spreadsheet would work, but I wanted a fast review without adding another copy of store data to a SaaS account.
My lightweight answer was a three-tool browser pass with Tiny Online Tools: inspect first, deduplicate by the columns that actually identify a record, then sort the resulting export into a handoff order. The tools run in the browser and do not require an account, which makes them a good fit for a one-off catalog cleanup.
First, decide what a duplicate means in this export
The dangerous version of CSV cleanup is treating every repeated-looking row as disposable. A Shopify export can legitimately repeat a handle when a product has variants, images, or multiple values. Before I touch a deduplicator, I make a copy of the original export and write down the rule I am trying to enforce.
For a contractor handoff, my rule might be: one row per unique email, one row per vendor + SKU, or one row per product handle only after variant rows have been removed upstream. The exact key depends on the job. A duplicate row is a data decision, not a visual impression.
A small preflight note is enough:
source: products-export-2026-10-19.csv
keep: latest row for matching SKU + vendor
review separately: rows with blank SKU
do not deduplicate: variant-specific inventory rows
That note also gives the contractor a way to challenge the assumption instead of silently inheriting it. This is the same kind of tiny guardrail I use before a Shopify tag cleanup: define the catalog rule before you apply a tool.
Inspect the shape before changing it
I open the file in Tiny Online Tools’ CSV Viewer. It turns the export into a readable table with headers, so I can quickly confirm the delimiter survived, identify the real identifier columns, and spot values that need their own review.
I am specifically looking for three things:
- A column pair that can safely identify a record, such as
SKUandVendor. - Blank identifiers, because those rows should not be merged by accident.
- Fields that look the same to a human but differ to the store, such as a variant title, option value, or image position.
If I find a strange delimiter or malformed export, I stop here. Duplicating a bad parse is worse than leaving a messy file alone. The same pause is useful when I hand off structured configuration: I use a no-upload JSON review workflow before assuming an automated transformation understood the shape.
Deduplicate on selected columns, not the whole row
Next I use the CSV Deduplicator. It lets me choose the columns to compare, choose case sensitivity, and keep either the first or last occurrence. That choice is the heart of the workflow.
For example, if the business rule is that a more recent supplier export wins, I keep the last occurrence after confirming the CSV order is chronological. If I am cleaning an accidentally repeated contact import, I may keep the first occurrence and preserve the original ordering. I do not choose “last” just because it sounds newer.
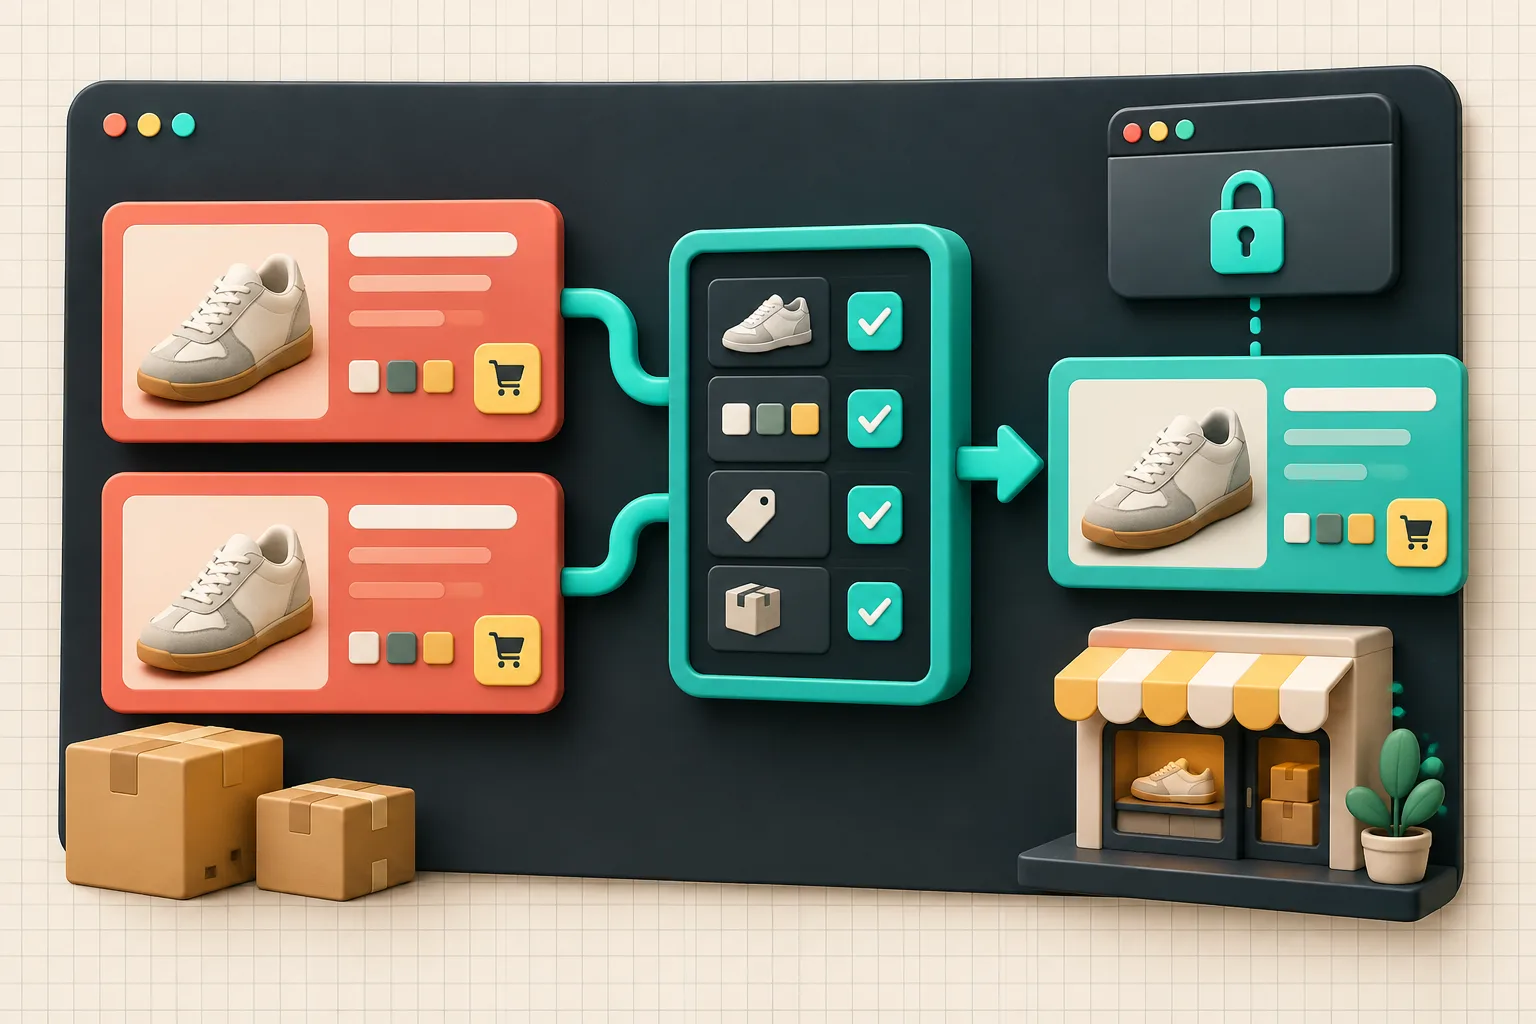
I also run a deliberately small test before the real export: five or ten rows with one known duplicate and one almost-duplicate. If the result removes the intended row and keeps the record I expect, the comparison key is probably sound. If it does not, I go back to the viewer and change the rule. This takes a minute and prevents an irreversible-looking spreadsheet surprise.
Tiny Online Tools reports how many duplicates it found and removed. I record those two counts in the handoff notes. A contractor should be able to say, “Why does this file have 812 rows instead of 837?” and get an answer without reconstructing the job from memory.
Sort the clean file for a human handoff
After deduplication, I use the CSV Sorter to sort by the field that makes review easiest—usually handle, vendor, or SKU. This does not make the file more correct, but it makes anomalies much easier to see. A missing SKU sticks out when the list is sorted by SKU; a repeated handle is obvious when all of its rows are adjacent.
Before I send anything, I open the downloaded CSV in the viewer again and spot-check:
- The expected columns still exist and remain in the original order when that matters.
- A known duplicate is gone, while a known legitimate variant row remains.
- The row count matches the deduplicator’s reported result.
- Blank-key records are still present for manual review.
This is intentionally more boring than trying to perfect a giant workbook. It is a small, repeatable browser workflow—similar in spirit to preparing product images for faster loading before upload: make a controlled delivery copy, preserve the source, and check the output before it leaves your hands.
What I send with the CSV
The clean CSV is not the whole handoff. I include the untouched original, the cleaned filename, and a compact README with the duplicate rule, the columns compared, whether first or last was kept, the before/after row counts, and the rows that need manual attention. If the contractor is importing back into Shopify, I also ask them to test the cleaned file in a non-production workflow before any broad update.
The useful part of this setup is not that a browser tool magically understands a catalog. It is that the repetitive mechanics stay local and quick while the operator keeps ownership of the decision. Start by bookmarking the CSV Viewer and CSV Deduplicator, then use the next messy export to make a one-page handoff note your future self can trust.